11

A collaborative group of industry researchers and engineering leaders has unveiled CAFE(S), a comprehensive framework designed to evaluate and improve the quality of context provided to artificial intelligence systems. Published in the journal ACM Queue, the framework arrives at a critical juncture in the evolution of software development, as the industry shifts from traditional coding to high-stakes human-agent collaboration. The paper, titled "CAFE(S): Your Agent Is Only as Good as Its Context," was co-authored by Max Kanat-Alexander of Capital One, Eirini Kalliamvakou of DX (formerly of GitHub), Margaret-Anne Storey of the University of Victoria, and Nicole Forsgren of Google. The initiative addresses a growing realization in the tech sector: while large language models (LLMs) have become increasingly powerful, their performance is fundamentally bottlenecked by the quality of the information—the context—fed into them.
Historically, knowledge management has been a persistent friction point in software engineering. Developers have long navigated the challenges of outdated documentation, ambiguous specifications, and contradictory requirements. In the pre-AI era, these deficiencies were often mitigated by human intervention; an engineer could seek clarification from a colleague to fill the gaps. However, the integration of AI agents into the development lifecycle has stripped away this buffer. In the current landscape, poor context leads to immediate, scalable, and quantifiable consequences. The authors of the CAFE(S) framework argue that context quality is no longer merely a matter of developer convenience but a critical factor in operational costs, legal liability, and cybersecurity.
The economic implications of context quality are primarily driven by the mechanics of "tokens," the basic units of text processed by AI models. Every token transmitted to an AI agent incurs a financial cost, and context is where these tokens accumulate most rapidly. The framework highlights the case of Notion, which optimized its context for reuse through prompt caching. By refining how context was delivered, Notion achieved a cost reduction of approximately 90 percent without sacrificing the quality of the AI’s output. This demonstrates that reading cached, well-structured context is significantly more efficient than the repetitive transmission of disorganized data.
Beyond economics, the framework addresses the rising legal risks associated with AI behavior. A landmark case cited in the research involves the British Columbia Civil Resolution Tribunal’s February 2024 ruling against Air Canada. The airline was found liable for a refund promised by its customer service chatbot, despite the fact that the promise contradicted the company’s actual policies. Air Canada’s defense—that the chatbot was a separate legal entity responsible for its own actions—was rejected. This precedent establishes that organizations are legally bound by the statements of their AI agents, making the fidelity of the context provided to those agents a matter of corporate liability.

Security represents the third major driver for the CAFE(S) framework. The authors point to EchoLeak (CVE-2025-32711), the first documented prompt injection attack to achieve real-world data exfiltration from a production AI system. In this instance, a specifically crafted email allowed an attacker to manipulate Microsoft 365 Copilot into pulling internal documents into its working context and subsequently leaking them. The incident proved that when untrusted or unvetted information enters an agent’s context, the agent will act on that information as if it were a legitimate instruction, creating a profound vulnerability.
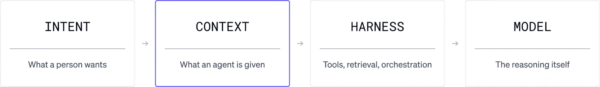
To address these challenges, the CAFE(S) framework conceptualizes the transition of human intent into agent behavior as a four-layer pipeline. At the top is "Intent," representing what a human user ultimately wishes to accomplish. This intent must be translated into "Context," the specific information representing tasks, constraints, and knowledge. This context is then processed by a "Harness"—the orchestration layer involving retrieval-augmented generation (RAG), tools, and memory—before finally reaching the "Model," which provides the underlying intelligence.
The researchers note that while significant academic and industrial effort has been poured into model improvement and harness engineering, the translation of intent into context has remained largely neglected. Traditional disciplines like knowledge management and information retrieval touch upon the edges of this problem, but they fail to answer whether the assembled context is actually "fit for purpose" for an AI agent. CAFE(S) fills this gap by defining five essential properties of high-quality context: Clarity, Actionability, Fidelity, Efficiency, and Security.
The first property, Clarity, dictates that context must be unambiguous and easy for the model to interpret. This involves using consistent terminology, avoiding jargon that might confuse the model, and providing clear relationships between different pieces of information. The second property, Actionability, ensures that the context contains everything necessary for the agent to complete the task. This includes providing a clear "definition of done" and explicit stopping criteria, preventing the agent from getting stuck in loops or producing incomplete work.
Fidelity, the third pillar, concerns the accuracy and timeliness of the information. Context must reflect the current state of the system rather than its historical state. Inaccurate context is a primary driver of AI "hallucinations," where the model produces confident but false information based on stale data. The fourth pillar, Efficiency, focuses on conciseness. With the "lost in the middle" phenomenon—where LLMs struggle to recall information buried in the center of long prompts—efficient context ensures that only the most relevant data is included, thereby improving both performance and cost-effectiveness.
The final property, Security, is placed in parentheses within the framework’s name—CAFE(S)—to signify its unique role. While the first four properties focus on the effectiveness of the agent, the security property focuses on its safety. It requires that context be vetted for untrusted input and that the agent’s access to data be strictly scoped to prevent unauthorized information from entering the context window.
The implementation of CAFE(S) requires a fundamental shift in how engineering teams view their data. The framework advocates for treating context as a first-class engineering artifact. This means context should be subject to the same rigors as source code: it must be owned by specific teams, undergo peer reviews, and be maintained as the system evolves. The authors outline three prerequisite stages for successful context engineering. First, information must be accessible; data locked in silos is useless to an agent. Second, the system must be capable of "cutting through the noise" to retrieve specific data slices across disparate systems. Finally, the knowledge must exist. No AI architecture can retrieve decisions made in undocumented meetings or "hallway conversations" that exist only in developers’ minds.
Once these prerequisites are met, organizations can apply specific strategies to improve quality across the CAFE(S) dimensions. For clarity, teams are encouraged to review prompts for ambiguity and define a shared glossary. To improve actionability, developers should provide explicit success criteria and "if-this-then-that" logic for edge cases. Fidelity can be maintained by auditing documentation for staleness and ensuring that RAG systems are pulling from the most recent data sources. Efficiency is improved by removing "fluff" from prompts and utilizing techniques like prompt caching. Security is bolstered by auditing agent permissions and implementing sanitization for any user-provided data that might enter the context.
The authors conclude that the CAFE(S) framework is intended to provide a shared vocabulary rather than a rigid measurement system. By establishing a definition of what high-quality context looks like, engineering teams can intervene before bad context leads to system failures. As the industry moves toward a future defined by agent autonomy, the framework suggests that providing clear, actionable, faithful, efficient, and secure context is the baseline requirement for delegating complex tasks to AI. Without these five properties, the authors warn, the risks of delegating authority to autonomous agents remain unacceptably high.