11

The rapid integration of artificial intelligence into software development lifecycles has shifted the focus of engineering productivity from human-to-human knowledge sharing to the precise assembly of information for machine consumption. A coalition of prominent researchers and industry leaders has released a new evaluative framework titled CAFE(S), designed to standardize the quality of context provided to AI agents. Co-authored by Max Kanat-Alexander of Capital One, Eirini Kalliamvakou of DX, Margaret-Anne Storey of the University of Victoria, and Nicole Forsgren of Google, the framework was recently published in ACM Queue. It arrives at a pivotal moment when the consequences of poor context management have evolved from minor developer inconveniences into significant financial, legal, and security liabilities for global enterprises.
Historically, knowledge management was viewed through the lens of human experience. Engineers frequently navigated outdated documentation, ambiguous specifications, and conflicting project requirements. While these issues hindered productivity, the "human-in-the-loop" factor allowed for real-time clarification; a developer could simply consult a peer to resolve a discrepancy. However, as AI agents take on more autonomous roles, they lack the innate ability to detect nuance or seek clarification unless explicitly instructed to do so. This shift has elevated context engineering from a secondary task to a primary discipline. The authors of the CAFE(S) framework argue that while context has always mattered, the scale at which AI systems operate means that errors are now amplified instantaneously, often carrying measurable costs and risks.
The economic implications of context quality are perhaps the most immediate concern for organizations deploying AI at scale. In the realm of Large Language Models (LLMs), information is processed in "tokens," which serve as the fundamental unit of currency for AI interactions. Every piece of context sent to an agent incurs a cost. The framework highlights a case study involving Notion, which re-engineered its context for reuse through prompt caching. By optimizing how context was stored and retrieved, the company achieved a 90 percent reduction in costs without sacrificing output quality. This demonstrates that efficiency in context is not merely a technical preference but a financial necessity, as reading cached context is significantly more affordable than retransmitting redundant data.
Beyond economics, the legal landscape is beginning to reflect the dangers of poor context. The CAFE(S) paper cites a landmark February 2024 ruling by the British Columbia Civil Resolution Tribunal. In this case, Air Canada was found liable for a refund promised by its customer service chatbot, despite the fact that the promise contradicted the airline’s official internal policies. Air Canada’s legal defense—that the chatbot was a separate legal entity responsible for its own actions—was rejected. The tribunal’s decision established a critical precedent: corporations are legally responsible for the outputs of their AI agents, regardless of whether those outputs were caused by internal logic errors or poor contextual data.

The third pillar of risk identified by the researchers is security. The emergence of "EchoLeak" (CVE-2025-32711) serves as a stark warning of how context can be weaponized. This incident represented the first documented real-world data exfiltration from a production AI system via prompt injection. In this scenario, a single crafted email—which the user never even opened—was processed by Microsoft 365 Copilot. The malicious content within the email caused the AI to pull sensitive internal documents into its active working context and subsequently leak them. This vulnerability highlights a fundamental truth in the AI era: if untrusted information becomes part of an agent’s context, the agent will act on that information as if it were a legitimate instruction.
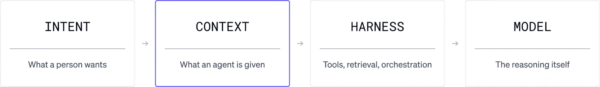
To address these challenges, the authors propose a conceptual pipeline that describes how human intent is translated into agent behavior. This pipeline consists of four distinct layers: Intent, Context, Harness, and Model. "Intent" represents what a human user ultimately wishes to accomplish. This must be translated into "Context," the specific information, constraints, and knowledge required for the task. The "Harness" then applies this context through orchestration, retrieval-augmented generation (RAG), and execution logic. Finally, the "Model" provides the underlying intelligence to produce a result.
The authors observe that while machine learning research focuses on the Model, and engineering teams focus on the Harness, the translation of Intent into Context has remained largely neglected. While Knowledge Management (KM) ensures information exists and Information Retrieval (IR) ensures it can be found, neither discipline confirms whether the resulting context is actually fit for the task at hand. The CAFE(S) framework is intended to fill this specific gap by defining five essential properties of high-quality context.
The first property is Clarity (C). Context must be unambiguous and provide specific instructions. When instructions are vague, models are forced to rely on probabilistic "guesses," which leads to hallucinations or inconsistent results. The second property is Actionability (A). High-quality context must define what a successful outcome looks like and provide the agent with the necessary tools and permissions to reach that "done" state. Without actionability, an agent may produce theoretically correct information that cannot be applied to the actual problem.
The third property is Fidelity (F). This refers to the accuracy and truthfulness of the context. Context must represent the system as it currently exists, not as it was designed years ago. Stale documentation is a primary enemy of fidelity. The fourth property is Efficiency (E). Given the token-based cost models of modern AI, context must be pruned to include only the most relevant data. Redundant or irrelevant information not only increases costs but can also "distract" the model, leading to lower-quality outputs.
The fifth property, Security (S), is placed in parentheses because it serves as a different type of filter. While the first four properties determine an agent’s effectiveness, the security property determines its safety. It involves auditing context for sensitive data leaks and ensuring that the context cannot be manipulated by external, untrusted sources to perform unauthorized actions. The researchers argue that a failure in the first four pillars makes an agent useless, but a failure in the security pillar makes it a threat.
Implementing the CAFE(S) framework requires a shift in how engineering teams view documentation and data. The authors suggest that context must be treated as a first-class engineering artifact, similar to source code. This means context must be accessible to the agent, the system must be capable of retrieving precise slices of data from scattered sources, and, perhaps most importantly, the knowledge must exist in a recorded format. Decisions made in "hallway conversations" or unrecorded meetings cannot be retrieved by an AI, creating a "context gap" that no amount of engineering can bridge.
To put the framework into practice, the researchers offer high-leverage strategies for each pillar. For Clarity, teams should avoid jargon and provide "few-shot" examples of good and bad outputs. For Actionability, they should define clear success criteria and verify that the agent has the required permissions. To ensure Fidelity, teams must implement automated systems to flag or prune outdated information. For Efficiency, prompt caching and the removal of redundant data are recommended. Finally, for Security, teams must enforce strict data boundaries and treat all external input as potentially malicious.
The CAFE(S) framework does not yet offer a quantitative measurement system; instead, it provides a qualitative vocabulary for engineering teams. The authors emphasize that before context can be measured, it must be defined. By providing a shared language, CAFE(S) allows teams to review context as part of their standard workflow and intervene before bad data leads to system failures.
As the industry moves toward greater human-agent collaboration, the authors conclude that high-quality context is the fundamental prerequisite for agent autonomy. While clear and secure context does not guarantee that an agent will succeed, the absence of it almost certainly guarantees failure. The framework serves as a baseline standard for organizations that wish to delegate complex work to AI systems safely and effectively. The full paper, "CAFE(S): Your Agent Is Only as Good as Its Context," is currently available through DX and ACM Queue, offering further guidance on how organizations can improve their context engineering practices to meet the demands of the AI-driven future.