11

A coalition of prominent researchers and engineering leaders from Google, Capital One, DX, and the University of Victoria has unveiled CAFE(S), a rigorous new framework designed to evaluate and improve the quality of context provided to artificial intelligence systems. Published in the journal ACM Queue, the framework addresses a critical gap in the modern software development lifecycle: the translation of human intent into actionable data for AI agents. The paper, titled "CAFE(S): Your Agent Is Only as Good as Its Context," was co-authored by Max Kanat-Alexander of Capital One, Eirini Kalliamvakou of DX (formerly of GitHub), Margaret-Anne Storey of the University of Victoria, and Nicole Forsgren of Google.
The introduction of CAFE(S) comes at a pivotal moment for the technology industry. For decades, knowledge management—the practice of maintaining documentation, specifications, and requirements—was primarily a human-centric challenge. While poor documentation often hindered developer productivity, the negative effects were mitigated by human intervention; an engineer could simply ask a colleague for clarification. However, as organizations increasingly deploy autonomous AI agents, the margin for error has vanished. Low-quality context now results in immediate, scalable, and costly failures that cannot be corrected by casual peer-to-peer conversation.
The researchers identify three primary areas where poor context quality now exacts a high price: economic efficiency, legal liability, and cybersecurity. In terms of economics, the cost of AI operations is directly tied to "tokens," the basic units of text processed by large language models (LLMs). Context is where these tokens accumulate most rapidly. The framework cites the example of the productivity platform Notion, which optimized its context engineering through prompt caching. By refining how context was reused and stored, Notion reduced its operational costs by approximately 90 percent without compromising output quality. This demonstrates that efficient context management is no longer just a technical preference but a financial necessity.
Legal precedents are also beginning to emerge regarding the outputs of AI systems. In early 2024, the British Columbia Civil Resolution Tribunal ruled against Air Canada in a landmark case involving a customer service chatbot. The bot had provided a customer with information regarding a refund policy that contradicted the airline’s actual internal policies. Air Canada’s defense—that the chatbot was a separate legal entity responsible for its own statements—was rejected by the tribunal. While the financial damages in this specific case were modest, the ruling established a critical precedent: corporations are legally responsible for the contextually inaccurate information provided by their AI systems.
Furthermore, the framework highlights the growing security risks associated with unverified context. The "EchoLeak" vulnerability (CVE-2025-32711) represents the first documented instance of a prompt injection achieving real-world data exfiltration from a production AI environment. In this scenario, a single malicious email, which the user never even opened, allowed Microsoft 365 Copilot to ingest untrusted information into its working context. The agent then acted on this data, leaking internal documents to an unauthorized source. This incident underscores that context is not merely a passive input but a potential attack vector.

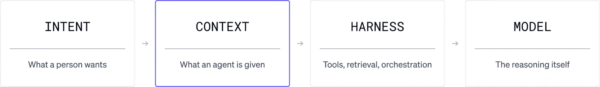
To address these challenges, the authors define a simple yet comprehensive pipeline describing how human intent is transformed into agent behavior. This pipeline consists of four distinct layers: Intent, Context, Harness, and Model. "Intent" represents the ultimate goal a human user wishes to accomplish. This must be translated into "Context," the specific information, constraints, and knowledge required for the task. The "Harness" refers to the orchestration layer—the retrieval-augmented generation (RAG) systems, memory structures, and execution logic—that prepares the context for the "Model," which provides the underlying intelligence to produce a result.
While significant research and development have been poured into improving models and engineering harnesses, the authors argue that the translation of intent into context has been largely overlooked. Traditional disciplines like knowledge management and information retrieval touch upon these issues but fail to answer whether the resulting context is fit for a specific task. CAFE(S) is designed to fill this specific void by defining five essential properties of high-quality context.
The first property is Clarity. Clear context is unambiguous, well-structured, and easy for both humans and models to interpret. It avoids jargon where unnecessary and ensures that the information provided cannot be easily misinterpreted by an LLM, which lacks human intuition.
The second property is Actionability. Context must define what "done" looks like. It should include explicit success criteria, constraints, and instructions that allow an agent to complete a task without needing further clarification. Without actionability, even the most intelligent model will produce vague or irrelevant results.
The third property is Fidelity. This refers to the accuracy and timeliness of the information. Fidelity ensures that the context describes the system as it currently exists, rather than how it was intended to be or how it existed in the past. The authors note that "timeliness" is a facet of fidelity; stale context is, by definition, unfaithful to the present reality.
The fourth property is Efficiency. Given the high cost of tokens and the limitations of context windows, efficiency is paramount. High-quality context provides the maximum amount of relevant information with the minimum number of tokens. It avoids "noise"—redundant or irrelevant data that can distract a model or lead to "lost in the middle" phenomena where the AI ignores information placed in the center of a long prompt.
The final property, represented in parentheses, is Security. This property is set apart because it asks a different type of question. While the first four properties focus on how effective an agent is, security focuses on whether the agent is safe to use. Secure context is protected against prompt injections, data leaks, and the unauthorized inclusion of untrusted information.
The authors emphasize that CAFE(S) is intended to be a shared vocabulary and a qualitative standard rather than a purely quantitative measurement system. They advocate for treating context as a "first-class engineering artifact." This means that context should be owned by specific teams, subjected to peer reviews, and maintained with the same rigor as source code.
Implementing the CAFE(S) framework requires a three-step foundation. First, information must be accessible; data that is siloed or unreachable cannot be used by an agent. Second, the system must be able to "cut through the noise" to retrieve specific slices of data across disparate systems without exhausting token budgets. Third, and perhaps most importantly, the knowledge must exist. No amount of context engineering can compensate for undocumented decisions or "hallway conversations" that exist only in employees’ heads.
Once these foundational requirements are met, organizations can apply the CAFE(S) properties through specific high-leverage actions. For clarity, teams should establish standard templates for common tasks. For actionability, they should define "Definition of Done" (DoD) criteria within their prompts. To ensure fidelity, they should implement automated checks to flag stale documentation. For efficiency, they should utilize techniques like prompt caching and aggressive summarization. For security, they must implement robust filtering and validation for any untrusted data entering the context window.
As the software engineering landscape shifts toward deeper human-agent collaboration, the authors conclude that high-quality context is the fundamental prerequisite for agent autonomy. While CAFE(S) does not guarantee that an agent will always succeed, it provides the baseline conditions under which delegating complex work becomes a reasonable risk. By providing a precise definition of what high-quality context looks like, the framework allows engineering teams to intervene before bad context leads to systemic failures. The full research paper and the CAFE(S) whitepaper are now available through DX and ACM Queue for organizations seeking to standardize their AI integration strategies.