11

The landscape of artificial intelligence in software engineering has reached a critical juncture where the success of autonomous agents is no longer determined solely by the underlying model’s intelligence, but by the quality of the information provided to it. In a significant collaborative effort between industry leaders and academic researchers, a new framework titled CAFE(S) has been released to provide a rigorous standard for evaluating the context assembled for AI systems. Published in ACM Queue, the framework was co-authored by Max Kanat-Alexander of Capital One, Eirini Kalliamvakou of DX (formerly of GitHub), Margaret-Anne Storey of the University of Victoria, and Nicole Forsgren of Google. This multidisciplinary team brings together perspectives from developer productivity research, large-scale enterprise engineering, and academic rigor to address a burgeoning crisis in the AI development lifecycle: the "context gap."
For decades, knowledge management has been a persistent friction point in software development. Engineers have long navigated the challenges of outdated documentation, ambiguous technical specifications, and fragmented requirements. Historically, however, the "cost" of poor documentation was mitigated by human intervention. If a developer encountered a gap in knowledge, they could seek clarification from a peer or rely on tribal knowledge shared within a team. The rise of Large Language Models (LLMs) and autonomous agents has stripped away this safety net. Agents cannot "go over and ask a peer" for clarification; they operate strictly on the data provided within their context window. Consequently, the repercussions of low-quality context are now immediate, measurable, and increasingly expensive.
The CAFE(S) framework identifies three primary drivers that have elevated the importance of context quality from a matter of convenience to a matter of operational necessity: economic efficiency (tokens), legal liability, and cybersecurity.
The economic driver is rooted in the "token economy." In the current AI paradigm, every piece of information sent to an agent incurs a cost, as context is the primary area where token accumulation occurs. The authors highlight the case of Notion, which re-engineered its context strategy for reuse through prompt caching. By optimizing how context was delivered, the company reduced its costs by approximately 90 percent without compromising output quality. This demonstrates that reading cached context is significantly more economical than the repetitive retransmission of redundant information.
The legal driver is exemplified by a landmark 2024 ruling by the British Columbia Civil Resolution Tribunal. In a case involving Air Canada, the airline was found liable for a refund promised by its customer service chatbot, even though the promise contradicted the company’s actual internal policies. Air Canada’s defense—that the chatbot was a separate legal entity responsible for its own statements—was rejected. This set a profound legal precedent: organizations are legally responsible for the "hallucinations" or errors of their AI agents, especially when those errors stem from poor context or conflicting policy data.

Finally, the security driver is highlighted by the emergence of "EchoLeak" (CVE-2025-32711), the first documented prompt injection to achieve real-world data exfiltration from a production AI system. In this instance, a single crafted email caused Microsoft 365 Copilot to ingest internal documents into its working context and subsequently leak them. This vulnerability underscores a terrifying reality: if untrusted or malicious information becomes part of an agent’s context, the agent will act on that information faithfully, potentially compromising the entire organization’s data integrity.
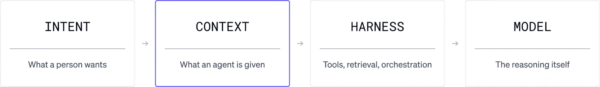
To address these challenges, the authors propose a conceptual pipeline that describes how human intent is transformed into agent behavior. This pipeline consists of four distinct layers: Intent, Context, Harness, and Model. While machine learning research focuses on improving the "Model" and harness engineering focuses on orchestration and retrieval, the "Context" layer has remained largely neglected. The CAFE(S) framework is designed to fill this gap, providing a standard for the translation of human intent into the specific information an agent needs to act.
The CAFE(S) framework is built upon five foundational properties. The first four properties—Clear, Actionable, Faithful, and Efficient—determine whether the context allows an agent to perform effective work. The fifth property, Security, is placed in parentheses to signify that it evaluates the same artifact but through the lens of safety rather than just performance.
Clear: Context must be precise and unambiguous. If the information provided is contradictory or uses vague terminology, the agent’s output will inevitably reflect that confusion. Clarity ensures that the model does not have to "guess" the meaning of its instructions.
Actionable: High-quality context must contain all the necessary information for the agent to complete the task. This includes clear "Definitions of Done" and access to the specific tools or data sets required for execution. Context that describes a problem without providing the means to solve it is not actionable.
Faithful: This property addresses the truthfulness of the context relative to the current state of the system. Stale documentation is a primary enemy of fidelity. If the context describes a software architecture as it existed two years ago rather than as it exists today, the agent will produce work that is fundamentally flawed.
Efficient: In the interest of both cost and performance, context must be concise. Agents have limited context windows, and "noisy" or redundant data can lead to a loss of focus on the primary task. Efficiency is about maximizing the "signal-to-noise" ratio in every token sent to the model.
(S)ecure: The security pillar asks whether the context is safe to use. This involves ensuring that sensitive data (PII) is not inadvertently included and that the context does not contain "poisoned" instructions that could lead to prompt injection or data exfiltration.
The authors emphasize that CAFE(S) is intended to be a vocabulary for engineering teams rather than a simple measurement system. To put the framework into practice, organizations must begin treating context as a "first-class engineering artifact." This means that context should be owned, reviewed, and maintained with the same rigor as source code.
The practical application of CAFE(S) involves several high-leverage strategies. For clarity and actionability, teams are encouraged to establish a "Definition of Done" for agent tasks and perform regular audits of the instructions provided to AI systems. To maintain fidelity, organizations must ensure that their knowledge bases are accessible and updated in real-time, bridging the gap between "hallway decisions" and recorded documentation. For efficiency, the use of prompt caching and the removal of redundant data are essential. For security, teams must implement strict filtering to ensure that untrusted data never enters the agent’s primary instruction set.
Furthermore, the framework highlights a fundamental prerequisite: the information must exist and be accessible. No amount of context engineering can surface decisions that live only in the minds of employees. Therefore, robust knowledge management remains the bedrock upon which AI agent autonomy is built.
In their concluding thoughts, the authors argue that as the industry shifts toward greater human-agent collaboration, high-quality context will become the primary determinant of whether delegating complex work to an AI is a reasonable risk. While the framework does not guarantee success—given the inherent unpredictability of LLMs—it provides the baseline conditions necessary for agents to function effectively. CAFE(S) offers a roadmap for engineering teams to intervene before bad context leads to systemic failures, ensuring that as agents become more autonomous, they remain grounded in clear, actionable, faithful, efficient, and secure information. The full paper, "CAFE(S): Your Agent Is Only as Good as Its Context," serves as a call to action for the industry to professionalize the way context is managed in the age of AI.