 11

The world is being fundamentally reshaped by artificial intelligence, and with this transformation comes the rapid invention of an entirely new lexicon to describe its advancements. Navigating product meetings, investment pitches, or industry panels today often involves encountering terms like LLMs, RAG, RLHF, and more recently, concepts such as "opaque recurrence"—a reasoning technique in OpenAI’s new Astra model that has reportedly alarmed AI safety researchers. This swift evolution of vocabulary can make even seasoned tech professionals feel a degree of insecurity. This comprehensive glossary serves as an attempt to demystify these terms, providing plain-English definitions of the AI jargon most likely to be encountered by those building with AI, investing in it, or simply striving to stay informed through industry publications and podcasts. This resource is designed to be a living document, updated regularly as the field continues to evolve, much like the dynamic AI systems it describes.
Artificial General Intelligence (AGI)
Artificial general intelligence, or AGI, remains a term with fluid definitions, yet it broadly refers to AI systems capable of surpassing average human performance across a wide spectrum of tasks. OpenAI CEO Sam Altman once characterized AGI as being "the equivalent of a median human that you could hire as a co-worker." OpenAI’s official charter provides a slightly more formal definition, describing AGI as "highly autonomous systems that outperform humans at most economically valuable work." Google DeepMind offers a similar, yet distinct, perspective, viewing AGI as "AI that’s at least as capable as humans at most cognitive tasks." This variation in definitions underscores the term’s nebulous nature, highlighting that even leading experts in AI research often grapple with a precise understanding of AGI.
AI Agent
An AI agent denotes a sophisticated tool that leverages AI technologies to execute a series of tasks on behalf of a user, extending far beyond the capabilities of a basic AI chatbot. Such agents can handle complex workflows like filing expenses, booking travel tickets or restaurant reservations, or even autonomously writing and maintaining code. However, the emergent nature of this domain means that the term "AI agent" can hold different meanings for different individuals, reflecting the various moving parts and ongoing infrastructure development required to realize its full potential. Fundamentally, the concept implies an autonomous system capable of orchestrating multiple AI components to complete multi-step objectives.
API Endpoints
API endpoints can be conceptualized as the "buttons" located on the backend of a software application that other programs can "press" to trigger specific actions. Developers utilize these interfaces to construct integrations, allowing one application to retrieve data from another, or enabling an AI agent to directly control third-party services without requiring manual human interaction with each interface. Many smart home devices and interconnected platforms incorporate these hidden buttons, even if they remain unseen by ordinary users. As AI agents become increasingly sophisticated, their ability to independently discover and utilize these endpoints opens up powerful, and sometimes unforeseen, possibilities for advanced automation.
Chain of Thought
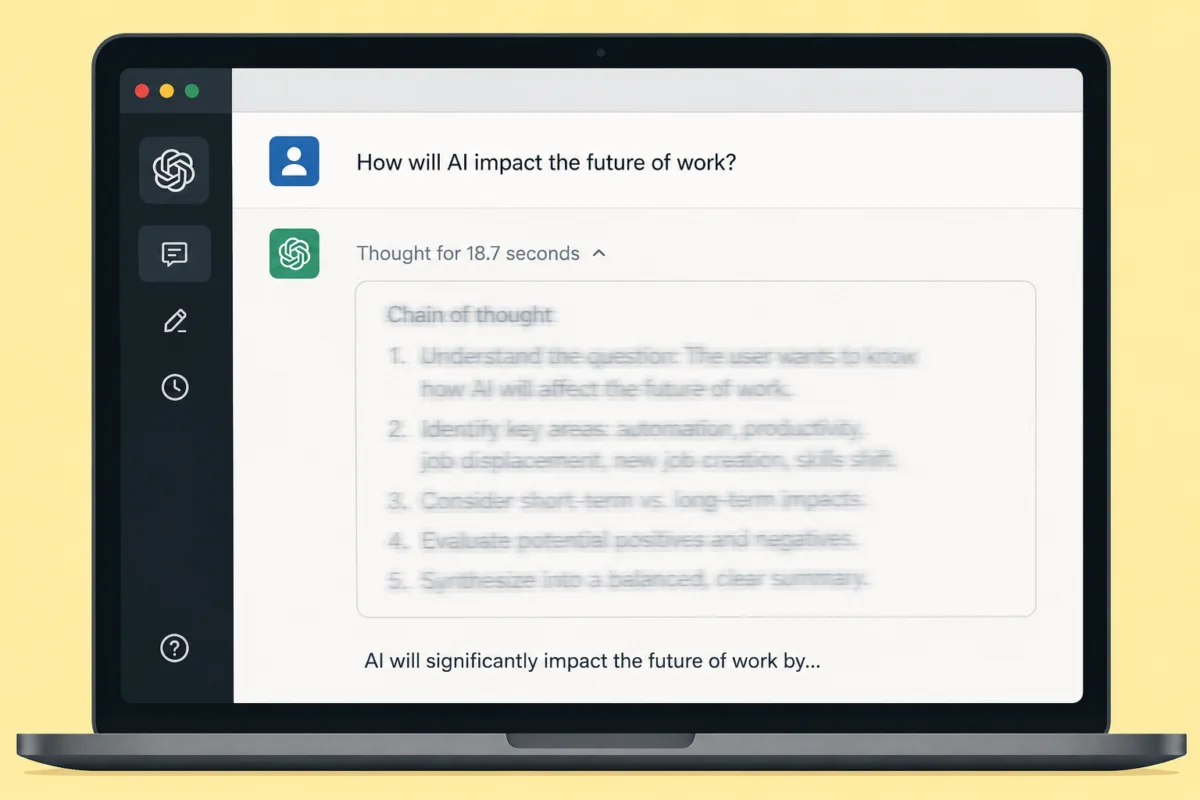
When presented with a simple question, a human brain can often provide an answer without extensive deliberation, such as "which animal is taller, a giraffe or a cat?" However, many problems necessitate intermediary steps, often requiring external aids like a pen and paper to arrive at the correct solution. For instance, calculating the number of chickens and cows a farmer has, given their total heads and legs, requires setting up and solving a simple equation. In the context of AI, chain-of-thought reasoning for large language models involves breaking down a complex problem into smaller, sequential intermediate steps. This method significantly enhances the quality and accuracy of the final output, particularly in tasks involving logic or coding, though it typically extends the time required to generate a response. Reasoning models are an evolution of traditional large language models, specifically optimized for chain-of-thought thinking through reinforcement learning. (See: Large Language Model)
Coding Agents
A coding agent is a specialized form of an "AI agent" applied to the domain of software development. Unlike systems that merely suggest code for human review and insertion, a coding agent possesses the autonomy to write, test, and debug code independently. It handles the iterative, trial-and-error processes that traditionally consume a significant portion of a developer’s day. These agents can operate across entire codebases, identifying bugs, executing tests, and implementing fixes with minimal human oversight. They can be thought of as exceptionally fast, tireless interns, though, like any intern, their work still requires human review.
Compute
"Compute" is a broad but critical term that generally refers to the indispensable computational power necessary for AI models to function. This processing capability is the lifeblood of the AI industry, enabling the training and deployment of powerful models. The term frequently serves as shorthand for the underlying hardware that provides this computational muscle, including Graphics Processing Units (GPUs), Central Processing Units (CPUs), Tensor Processing Units (TPUs), and other forms of specialized infrastructure that constitute the foundation of modern AI.
Deep Learning
Deep learning is a sophisticated subset of machine learning characterized by AI algorithms designed with a multi-layered, artificial neural network (ANN) structure. This architecture allows deep learning models to identify more complex correlations within data compared to simpler machine learning systems, such as linear models or decision trees. The design of deep learning algorithms draws inspiration from the intricate, interconnected pathways of neurons in the human brain. These models are capable of autonomously identifying important characteristics in data, eliminating the need for human engineers to explicitly define these features. The structure also supports algorithms that can learn from errors, iteratively improving their outputs through repetition and adjustment. However, deep learning systems demand vast quantities of data (often millions or more data points) to yield optimal results and typically require longer training times than simpler machine learning algorithms, leading to higher development costs. (See: Neural Network)
Diffusion
Diffusion is the core technology powering many of today’s generative AI models for art, music, and text. Inspired by principles from physics, diffusion systems systematically "destroy" the structural integrity of data—such as photos or songs—by progressively adding noise until the original data is unrecognizable. While physical diffusion is spontaneous and irreversible (e.g., dissolved sugar cannot be easily reformed into a cube), diffusion systems in AI are designed to learn a "reverse diffusion" process. This allows them to recover the original data from noise, thereby gaining the ability to generate new, coherent data from random noise.
Distillation
Distillation is a technique employed to transfer knowledge from a larger, more complex AI model (the "teacher") to a smaller, more efficient model (the "student"). This process involves sending queries to the teacher model and recording its outputs. These outputs, sometimes validated against a dataset for accuracy, are then used to train the student model to emulate the teacher’s behavior. Distillation enables the creation of compact, high-performing models based on their larger counterparts with minimal loss of capability. This method is believed to be how OpenAI developed GPT-4 Turbo, a faster iteration of GPT-4. While all AI companies utilize distillation internally, its use by some to replicate competitor models may violate the terms of service for AI APIs and chat assistants.
Fine-tuning
Fine-tuning refers to the process of further training an existing AI model to optimize its performance for a more specific task or domain than its initial training encompassed. This is typically achieved by feeding the model new, specialized, and task-oriented data. Many AI startups leverage large language models as a foundational base for commercial products, then enhance their utility for a particular sector or task by supplementing the initial training with fine-tuning based on their unique domain-specific knowledge and expertise. (See: Large Language Model [LLM])
Generative Adversarial Network (GAN)
A GAN, or Generative Adversarial Network, is a machine learning framework central to significant advancements in generative AI, particularly in producing highly realistic data, including deepfake technologies. GANs operate using two competing neural networks: a generator network, which creates outputs from its training data, and a discriminator network, which evaluates these outputs. The two models are programmed to engage in a structured contest: the generator strives to produce outputs that can fool the discriminator into believing they are real, while the discriminator works to accurately identify artificially generated data. This adversarial process optimizes AI outputs for realism without requiring additional human intervention. GANs are most effective for narrower applications, such as generating realistic images or videos, rather than general-purpose AI.
Hallucination
"Hallucination" is the AI industry’s term for instances where AI models generate information that is factually incorrect or entirely fabricated. This issue poses a significant challenge to AI quality and reliability. Hallucinations can produce misleading GenAI outputs, potentially leading to real-world risks, such as harmful medical advice from a health-related query. This problem is thought to stem from gaps or inconsistencies in the models’ training data. The prevalence of hallucinations is a driving factor behind the development of increasingly specialized and/or vertical AI models—domain-specific AIs with narrower expertise—as a strategy to mitigate knowledge gaps and reduce the risks of disinformation.
Inference
Inference is the operational phase of an AI model, where it is run to make predictions or draw conclusions from previously unseen data. Crucially, inference cannot occur without prior training; a model must first learn patterns from a given dataset before it can effectively extrapolate from that training data. Various types of hardware can perform inference, ranging from smartphone processors to powerful GPUs and custom-designed AI accelerators. However, the efficiency varies significantly; very large models would take considerably longer to make predictions on, for example, a laptop compared to a cloud server equipped with high-end AI chips. (See: Training)
Large Language Model (LLM)
Large language models, or LLMs, are the foundational AI models that power popular AI assistants such as ChatGPT, Claude, Google’s Gemini, Meta’s AI Llama, Microsoft Copilot, and Mistral’s Le Chat. When a user interacts with an AI assistant, they are engaging with an LLM that processes their request, either directly or by leveraging various available tools like web browsing or code interpreters. LLMs are deep neural networks composed of billions of numerical parameters (also known as weights) that learn the intricate relationships between words and phrases, constructing a multi-dimensional representation of language. These models are developed by encoding patterns discovered in vast datasets comprising billions of books, articles, and transcripts. When prompted, an LLM generates the most probable pattern that aligns with the given input. (See: Neural Network)
Memory Cache
Memory cache refers to a crucial process designed to enhance inference, the operation by which AI generates responses to user queries. Essentially, caching is an optimization technique aimed at improving inference efficiency. AI computations involve high-octane mathematical calculations, and each execution consumes processing power. Caching reduces the number of redundant calculations a model needs to perform by saving specific calculations for subsequent user queries and operations. Various forms of memory caching exist, with KV (key-value) caching being a prominent example, particularly in transformer-based models. KV caching boosts efficiency and accelerates results by minimizing the time and algorithmic effort required to generate answers to user questions. (See: Inference)
Model Context Protocol (MCP)
Model Context Protocol, or MCP, is an open standard that facilitates the connection of AI models to external tools and data sources, such as user files, databases, or applications like Slack and Google Drive. Its key innovation is enabling these connections without requiring developers to build custom connectors for every unique pairing. It can be thought of as a universal "USB-C port" for AI. Anthropic introduced MCP in 2024 and subsequently transferred its stewardship to the Linux Foundation. Since its inception, it has been adopted by major players like OpenAI, Google, and Microsoft, establishing it as one of the most rapidly spreading standards in recent AI history.
Mixture of Experts (MoE)
Mixture of Experts (MoE) describes a model architecture that partitions a neural network into numerous smaller, specialized sub-networks, or "experts." For any given task, only a select handful of these experts are activated. Instead of routing every request through the entire model—analogous to consulting an entire office for every question—an MoE model incorporates a built-in "router" that intelligently selects the most relevant specialists for the job. This design enables the creation of exceptionally large models that maintain relative speed and cost-efficiency, as only a fraction of the network is actively processing at any one time. Mistral AI’s Mixtral model is a well-known implementation, and OpenAI’s more recent GPT models are widely believed to incorporate some form of this approach, though the company has not officially confirmed it. (See: Neural Network, Deep Learning)
Neural Network
A neural network refers to the multi-layered algorithmic structure that underpins deep learning and, more broadly, the recent surge in generative AI tools following the emergence of large language models. The fundamental concept of designing data processing algorithms inspired by the densely interconnected pathways of the human brain dates back to the 1940s. However, the true potential of this theory was unlocked much more recently with the rise of graphical processing hardware (GPUs), initially driven by the video game industry. These chips proved exceptionally well-suited for training algorithms with significantly more layers than was previously feasible. This capability enabled neural network-based AI systems to achieve vastly superior performance across diverse domains, including voice recognition, autonomous navigation, and drug discovery. (See: Large Language Model [LLM])
Neuralese
Neuralese is a hypothetical worst-case scenario where an AI model conducts its reasoning entirely using its internal numeric representations rather than human-readable language. This would render its thought processes a complete "black box." Currently, no deployed model operates in this manner; OpenAI has stated that its Astra model (released in September 2026, and notable for its early adoption of "opaque recurrence") maintains a legible chain of thought, pushing back against comparisons to neuralese. However, safety researchers point to Astra’s use of opaque recurrence—defined directly below—as a significant initial step in that direction, which explains the term’s increased prominence since the reporting around Astra’s launch.
Opaque Recurrence
Opaque recurrence describes a reasoning technique where an AI model repeatedly loops the same query through its internal layers instead of processing information step-by-step in plain language. This method offers increased efficiency, allowing smaller models to achieve performance beyond their typical weight class while consuming less computational power. However, it generates significantly fewer readable traces of its reasoning compared to a standard chain of thought (the detailed commentary often provided by chatbots). This lack of transparency is a concern for safety researchers, as these logs are a crucial tool for identifying and rectifying misbehavior, and opaque recurrence could make such oversight considerably more challenging. (See: Chain of Thought)
Open Source
Open source refers to software—and increasingly, AI models—where the underlying code is made publicly available for anyone to use, inspect, or modify. In the AI domain, Meta’s Llama family of models serves as a prominent example, echoing historical parallels like the Linux operating system. Open source approaches empower researchers, developers, and companies globally to build upon one another’s work, thereby accelerating progress and enabling independent safety audits that are difficult to achieve with closed systems. Conversely, closed source means the code remains private; users can utilize the product but cannot examine its internal workings, as is the case with OpenAI’s GPT models. This distinction has become one of the defining debates within the AI industry.
Parallelization
Parallelization involves performing multiple tasks concurrently rather than sequentially—akin to having ten employees work on different parts of a project simultaneously, rather than one employee completing each task in order. In AI, parallelization is fundamental to both training and inference processes. Modern GPUs are specifically engineered to execute thousands of calculations in parallel, which is a primary reason they have become the hardware backbone of the industry. As AI systems become more complex and models grow larger, the capacity to parallelize work across numerous chips and machines has emerged as a critical factor in determining the speed and cost-effectiveness of model development and deployment. Research into more advanced parallelization strategies is now a distinct field of study.
RAMageddon
RAMageddon is a colloquial term for a concerning trend sweeping the tech industry: an escalating shortage of random access memory (RAM) chips, which are essential components for virtually all modern technological products. With the explosive growth of the AI industry, major tech companies and AI laboratories are acquiring such vast quantities of RAM to power their data centers that a significant scarcity has emerged for other sectors. This supply bottleneck has driven up prices for remaining RAM, impacting various industries. For instance, the gaming sector has seen major companies raise console prices due to difficulties in sourcing memory chips. Consumer electronics face potential dips in smartphone shipments, possibly the largest in over a decade, because of memory shortages. General enterprise computing also struggles to secure sufficient RAM for its data centers. This surge in prices is expected to persist until the shortage alleviates, though current indications suggest no immediate end to this challenge.
Recurrent Depth
Recurrent depth is a more technical designation for the same underlying method as opaque recurrence, involving the iterative looping of a query through a model’s internal layers instead of a linear, language-based reasoning process. Media outlets often use these two terms interchangeably, hence its inclusion here. While "recurrent depth" is the engineering term, "opaque recurrence" specifically highlights the associated safety concerns. (See: Opaque Recurrence, Chain of Thought)
Recursive Self-Improvement (RSI)
Similar to AGI, recursive self-improvement (RSI) represents a theoretical threshold for AI intelligence and its potential autonomy from human oversight. In an RSI scenario, AI models begin to enhance themselves without human intervention, leading to an exponential acceleration in their capabilities and autonomy. Some narratives depict this as a cataclysmic event akin to the singularity, where AI models become impervious to external control. However, RSI also describes a more tangible engineering goal: whether an AI model can design its own successor. A number of recent AI startups have embarked on building recursively self-improving models, though most dismiss the apocalyptic implications, presenting RSI as simply the next frontier for research.
Reinforcement Learning
Reinforcement learning is a method of AI training where a system learns through trial and error, receiving "rewards" for correct actions—much like training a pet with treats, but in this case, the "pet" is a neural network and the "treat" is a mathematical signal indicating success. Unlike supervised learning, which relies on a fixed dataset of labeled examples, reinforcement learning enables a model to explore its environment, perform actions, and continuously adjust its behavior based on the feedback it receives. This approach has proven exceptionally powerful for training AI to master games, control robots, and, more recently, to refine the reasoning abilities of large language models. Techniques such as reinforcement learning from human feedback (RLHF) are now integral to how leading AI laboratories fine-tune their models to be more helpful, accurate, and safe.
Token
In the realm of human-machine communication, a fundamental challenge lies in bridging the gap between human language and the complex algorithmic processes of AI programs. Tokens serve as the basic building blocks of human-AI interaction, representing discrete segments of data that have been processed or generated by an LLM. They are created through a process called tokenization, which breaks down raw text into manageable, bite-sized units that a language model can effectively digest, analogous to how a compiler translates human language into binary code comprehensible to a computer. In enterprise contexts, tokens also dictate cost; most AI companies bill for LLM usage on a per-token basis, meaning increased usage translates to higher expenses for businesses.
Token Throughput
As established, tokens are the small segments of text—often parts of words rather than entire words—into which AI language models decompose language prior to processing. For practical purposes in understanding AI workloads, they are roughly analogous to "words." Throughput, in general, refers to the quantity of work that can be processed within a given timeframe. Therefore, token throughput is essentially a measure of how much AI work a system can handle concurrently. Achieving high token throughput is a primary objective for AI infrastructure teams, as it directly influences how many users a model can serve simultaneously and the speed at which each user receives a response. AI researcher Andrej Karpathy has expressed a sense of anxiety when his AI subscriptions sit idle, mirroring his feelings as a graduate student when expensive computer hardware was underutilized—a sentiment that underscores why maximizing token throughput has become a central preoccupation in the field.
Training
Developing machine learning AIs involves a crucial process known as training. In essence, training refers to the systematic feeding of data into a model, allowing it to learn patterns and subsequently generate useful outputs. This process involves the system identifying and responding to characteristics within the data, enabling it to adapt its outputs toward a desired goal—whether that’s recognizing images of cats or composing a haiku on demand. Training can be a costly endeavor due to the enormous volume of inputs required, a trend that has been continuously escalating. Consequently, hybrid approaches, such as fine-tuning a rules-based AI with targeted data, can help manage costs without necessitating development entirely from scratch. (See: Inference)
Transfer Learning
Transfer learning is a technique where a previously trained AI model is utilized as the foundational starting point for developing a new model intended for a different, though typically related, task. This approach allows knowledge acquired during earlier training cycles to be effectively reapplied. Transfer learning can generate significant efficiency savings by shortening the model development process. It is also particularly valuable in scenarios where data for the specific task the new model is being developed for is somewhat limited. However, it is important to acknowledge the limitations of this approach: models relying on transfer learning for generalized capabilities will likely require additional training on domain-specific data to achieve optimal performance in their area of focus. (See: Fine-tuning)
Validation Loss
Validation loss is a numerical metric that indicates how effectively an AI model is learning during its training phase, with lower values signifying better performance. Researchers closely monitor this metric as a real-time report card, using it to make critical decisions, such as when to cease training, when to adjust hyperparameters, or when to investigate potential problems within the model. One of its key functions is to help flag overfitting, a condition where a model memorizes its training data rather than genuinely learning generalizable patterns. This can be understood as the difference between a student who truly grasps the material and one who merely memorized last year’s exam; validation loss helps reveal which scenario your model is exhibiting.
Weights
Weights are fundamental to AI training, serving as numerical parameters that determine the degree of importance (or "weight") assigned to different features (or input variables) within the data used to train the system. By doing so, they significantly shape the AI model’s output. In essence, weights define what is most salient in a dataset for a given training task, achieving their function by applying multiplication to inputs. Model training typically commences with randomly assigned weights, but as the process unfolds, these weights are iteratively adjusted as the model strives to produce an output that more closely matches the target. For example, an AI model designed to predict housing prices, trained on historical real estate data for a specific location, would incorporate weights for features such as the number of bedrooms and bathrooms, whether the property is detached or semi-detached, and the presence of parking or a garage. Ultimately, the weights assigned by the model to each of these inputs reflect their influence on the property’s value, based on the provided dataset.